
Why Schema Markup Is a Must-Have for Modern SEO Strategies
Schema Markup: From Rich Results to AI Citations
How structured data became the connective tissue between your content and every modern search surface — traditional SERPs, AI Overviews, and Knowledge Graphs alike.
- Schema markup is no longer just about star ratings in search results. It is the primary signal Google’s AI systems use to parse, verify, and cite your content.
- Google AI Overviews now appear on roughly 30% of queries. Pages with correct JSON-LD schema have a measurably higher probability of being cited as sources.
- Google confirmed in April 2025 that “structured data gives an advantage in search results.” That statement ended the debate.
- The March 2026 core update deprecated some schema types while elevating entity-based schema (Organization, Person, SameAs). The strategy has changed. This guide reflects the current reality.
- JSON-LD is the only implementation format worth your time in 2026.
Should You Even Do This?
Before spending any time on schema implementation, here is a fast decision filter. Most guides skip this. They should not.
The answer for the vast majority of sites — especially those trying to grow organic traffic and appear in AI-generated results — is a clear yes. The question is not whether to implement schema but which types, in which order, and to what depth.
What Schema Markup Actually Is (and What It Is Not)
Schema markup is structured data code added to HTML that describes the meaning of your content to machines. It uses a shared vocabulary defined at Schema.org — a collaborative project maintained by Google, Microsoft, Yahoo, and Yandex since 2011. When Google’s crawler reads your page, it reads two layers: the visible content humans see and the schema code machines read. Schema makes the second layer explicit and unambiguous.
There are three ways to implement structured data: JSON-LD (JavaScript Object Notation for Linked Data), Microdata, and RDFa. In practice, only one of these deserves attention.
Google’s own documentation recommends JSON-LD as the preferred format. It lives in a separate <script> tag, which means it does not interfere with your HTML markup and can be injected dynamically. Microdata and RDFa require weaving attributes into your existing HTML — an approach that creates maintenance debt with no technical upside. Use JSON-LD. Full stop.
A common misconception is that schema directly influences rankings. It does not, and Google has been consistent on this point. What schema does influence is what Google is able to do with your content downstream: display rich results, include pages in Knowledge Graph entities, surface content in AI Overviews, and recognize your organization as a verified entity. Those outcomes drive measurable traffic gains even without a single ranking position change.
Why 2026 Changed the Stakes
The case for schema markup has always existed. But between mid-2024 and the first quarter of 2026, three developments transformed it from a nice-to-have into a strategic necessity.
1. AI Overviews went from experiment to standard
Google’s AI Overviews began appearing on roughly 13.1% of US desktop queries in March 2025, up from 6.5% just two months earlier. By early 2026, that figure had grown to approximately 30% of all queries. When an AI Overview occupies the top slot, the first organic result’s CTR compresses significantly — according to First Page Sage’s 2025 analysis, to a range of roughly 38-43%. Miss the AI Overview entirely, and the clicks you lose go to whoever does appear in it.
The connection to schema is direct. Pages with clean, accurate JSON-LD are easier for Google’s generative AI to extract facts from, which raises their probability of being cited as a source. A controlled experiment published by Search Engine Land in September 2025 tested three nearly identical pages with the same content and keyword difficulty — only the variable of schema implementation differed. Only the page with JSON-LD appeared in a Google AI Overview. It also ranked third in standard organic results. The page with no schema was not indexed.
2. Both Google and Microsoft made explicit statements
In spring 2025, both companies confirmed that structured data is critical for their generative AI features because it is “efficient, precise, and easy for machines to process.” The April 2025 Google Search Liaison statement added that “structured data gives an advantage in search results.” These statements carry weight precisely because Google rarely concedes ground on what influences search outcomes.
3. The March 2026 core update redefined what schema is for
Google’s March 2026 core update completed on March 12 and produced the most significant shift in structured data strategy since rich snippets launched. FAQ rich result impressions dropped by nearly half across tracked sites. How-To rich results disappeared for pages where the markup described supplementary rather than primary content. At the same time — and this largely went unnoticed — sites with clean, accurate entity schema saw measurably improved citation rates in Google’s AI Mode. The update did not kill schema. It changed what schema is for.
The strategic conclusion from these three developments is that schema now serves two distinct purposes that require different types, different validation approaches, and different success metrics. Understanding the split is the core insight most 2026 schema guides miss.
Job 1 — Rich Result Eligibility. Schema types that match your primary content type (Product, Recipe, Event, Review, VideoObject) and meet Google’s quality thresholds. These drive enhanced SERP listings and measurable CTR lifts. Success metric: rich result impressions in Search Console.
Job 2 — Entity Trust Signals for AI Citation. Organization, Person, Article, BreadcrumbList, and SameAs identifiers. These help Google’s AI systems resolve who you are, verify your claims, and select you as a citation source. Success metric: AI Overview appearance rate, Knowledge Panel accuracy.
Most sites in 2026 are optimized for Job 1 only. The competitive gap is in Job 2.
Note on statistics: citation lift figures reflect third-party observational studies, not direct Google disclosures. Treat as directional signals, not absolute benchmarks. Percentages vary significantly by industry and implementation quality.
The Schema Types That Still Matter
Google has deprecated several schema types over the past three years, including general-use FAQ and How-To rich results for most site categories, Job Posting eligibility changes, and seven additional types announced in November 2025. What remains is a leaner, higher-value set.
| Schema Type | Job 1: Rich Result | Job 2: Entity Trust | Priority Tier |
|---|---|---|---|
| Organization | Limited | High | ▲ Deploy First |
| BreadcrumbList | Yes — cleaner URL display | Moderate | ▲ Deploy First |
| Article / BlogPosting | Moderate — helps Discover | High — AI citation signals | ▲ Deploy First |
| Product | High — price, availability, reviews | Moderate | ▲ Deploy First (e-commerce) |
| Review / AggregateRating | High — star ratings in SERP | Moderate | ▲ Deploy First (if eligible) |
| LocalBusiness | High — local knowledge panel | High — AI local recommendations | ▲ Deploy First (local) |
| Event | High — Events carousel | Moderate | Deploy when relevant |
| VideoObject | High — video carousels | Moderate | Deploy when relevant |
| Recipe | High — rich recipe display | Low | Deploy when relevant |
| Person | Rarely direct | High — E-E-A-T author signals | Deploy for author pages |
| FAQPage | Deprecated for most sites (2023) | Minimal | Do not use (general sites) |
Organization and Person schema with SameAs identifiers have become the highest-leverage implementation type following the March 2026 update. Sites with clear entity disambiguation saw measurable improvements in both AI Mode citations and Knowledge Panel accuracy. If you have not implemented these, they are your most immediate opportunity.
How This Actually Works Together
Most schema implementations are fragmented. An SEO adds FAQ schema to a few posts, leaves the organization entity undefined, and wonders why results are inconsistent. The reason is that schema works as a system, not a collection of isolated tags. Here is the complete flow.
The Schema Signal Chain
- Entity Declaration (Organization / Person / LocalBusiness) Define who you are. Use SameAs to link to your Wikidata entry, LinkedIn, Crunchbase, and Google Business Profile. This creates the entity anchor that all other schema builds on. Without it, Google is inferring your identity from unstructured text.
- Site Structure Signals (BreadcrumbList) Deploy on every page, not just blog posts. Replaces raw URL slugs in SERP display with a readable breadcrumb path. Also communicates site hierarchy to crawlers, which influences how Google understands the topical authority of individual pages.
- Content Type Declaration (Article / Product / Event) Declare the primary type of each page. For articles, include datePublished, dateModified, author (linked to a Person entity), and headline. This data feeds Google’s freshness signals and AI citation source selection.
- Rich Result Enhancement (Review / Product / Video) Layer product price, availability, and aggregate ratings where eligible. These are the schema types that produce visible SERP enhancements. They require compliance with Google’s quality policies — particularly for reviews, which face active enforcement.
- Validation and Monitoring Test with Google’s Rich Results Test after every deployment. Monitor the Enhancements section of Search Console weekly. Schema errors are silent failures — they do not surface in standard SEO reports and can eliminate rich result eligibility without warning.
Integration Type
The integration between your CMS and your schema is either native, manual, or semi-automated. Each has different trade-offs.
| Integration Type | How it works | Best For | Friction Points |
|---|---|---|---|
| Native (CMS plugin) | Schema generated automatically from existing fields (title, author, product data) | WordPress, Shopify, standard use cases | Limited control over custom types; may generate outdated types if plugin not maintained |
| Semi-automated (template injection) | JSON-LD template with dynamic variables pulled from CMS data layer | Medium-large sites needing consistency across thousands of pages | Requires developer involvement; data mismatches create bulk errors |
| Manual (hardcoded JSON-LD) | Schema written and maintained page-by-page | High-priority pages, complex entity structures, unusual schema types | Does not scale; prone to drift when content updates without schema updates |
In practice: use native/plugin for the baseline types (Organization, Article, BreadcrumbList), manual for the homepage entity block and key landing pages, and semi-automated for product catalog or event pages where volume is high.
A Minimal JSON-LD Example
This is what a correct Organization entity block looks like in practice. The SameAs array is what connects your schema to the broader entity graph.
<script type="application/ld+json">{ "@context": "https://schema.org", "@type": "Organization", "name": "Your Company Name", "url": "https://www.yoursite.com", "logo": "https://www.yoursite.com/logo.png", "sameAs": [ "https://www.linkedin.com/company/yourcompany", "https://www.wikidata.org/wiki/QXXXXXXX", "https://www.crunchbase.com/organization/yourcompany" ], "contactPoint": { "@type": "ContactPoint", "telephone": "+1-555-000-0000", "contactType": "customer service" }}</script>Implementation: The 80% Solution Stack
The following three tools handle the core schema workflow for most sites. No tool handles everything. The gaps between them are where your attention belongs.
For monitoring AI Overview appearances and citation frequency, the 80% stack above is blind. Tools like the Semrush AI Toolkit, SE Ranking’s AI Overview tracker, and BrightEdge Generative Parser are emerging to fill this gap. None are fully mature as of May 2026. Pricing and feature availability last checked: May 2026.
Limitations and What People Get Wrong
Schema guides tend to oversell outcomes. Here is a more honest accounting of what schema can and cannot do, and where implementations commonly fail.
Schema is necessary but not sufficient for rich results
Valid schema makes a page eligible for rich result display. It does not guarantee it. Google’s algorithms apply additional quality thresholds — content quality, page authority, compliance with specific guidelines for each rich result type — before awarding enhanced display. A site with perfect schema and thin content will not earn rich results. A high-authority page with imperfect schema often will.
AI citation effects are real but not uniform across platforms
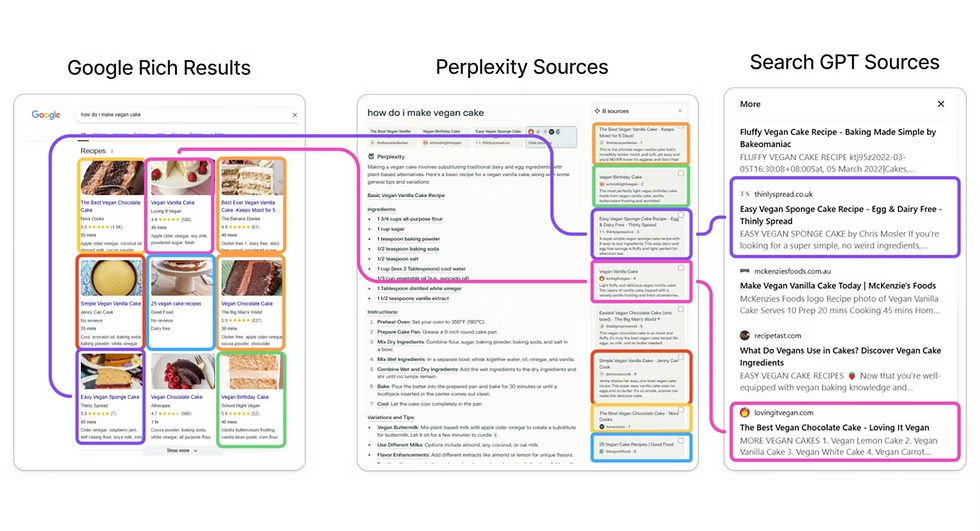
Research presented at BrightonSEO in April 2026 found that a sitewide schema rollout across 2,000+ URLs produced a significant increase in Google AI Overviews citations while citation rates actually dropped on ChatGPT, Gemini standalone, and Copilot. Perplexity showed no impact. If your traffic strategy depends on AI discovery across multiple platforms, schema alone is insufficient — and optimizing for Google’s systems may not transfer to others.
Outdated schema can be actively harmful
Schema that describes content inaccurately — particularly review markup on pages that do not actually contain reviews, or How-To markup on informational pages — has been actively demoted or manually actioned at scale following the March 2026 update. The risks of wrong schema now outweigh the risks of no schema in specific situations. If you are unsure whether your content is genuinely eligible for a rich result type, check Google’s specific guidelines before implementing.
The partial implementation trap
Adding FAQ schema to one page while leaving your Organization and Person entities undefined is a common pattern. It leaves the highest-leverage signals — entity trust and AI citation candidacy — on the table while spending effort on rich result types that may not return significant traffic for your category. In many workflows, the entity layer (Organization, Person, SameAs) delivers more measurable impact than any individual content-type schema.
FAQ
Final Thoughts
Here is the uncomfortable reality that most schema articles will not tell you directly: the window for easy competitive advantage from schema markup is closing. In 2025, fewer than half of all web pages used JSON-LD. By 2026, that figure has risen to over 40%. The gap between schema-optimized and schema-absent sites is narrowing in the places where it was easiest to win — basic rich results for articles and breadcrumbs.
Where the gap is actually widening is the entity layer. Most sites have still not built complete Organization entities with cross-referenced SameAs identifiers. Most author pages do not have Person schema. Most content does not explicitly declare its author’s credentials in machine-readable form — which is exactly the signal that Google’s E-E-A-T evaluation and AI citation systems look for first.
The sites that will dominate AI Overview citations over the next two years are not the ones that have deployed the most schema types. They are the ones whose entities are unambiguously declared, whose content types are precisely described, and whose authors are verifiably real. Schema is how you communicate all three in a language machines read without interpretation errors.
If your organization exists in Google’s Knowledge Graph as a verified entity with SameAs cross-references, your content is substantially more likely to appear in AI citations than technically superior content from an unverified entity. Entity declaration is no longer an advanced SEO task. It is foundational. If you have been treating it as optional, that position is now difficult to defend.
Start with entity schema. Validate everything. Monitor Search Console. Then layer content-type markup where your pages genuinely qualify. That sequence — not the reverse — is what delivers compounding results in 2026 and beyond.
Primary Sources
- Schema App — The Semantic Value of Schema Markup in 2025 — CTR impact data from quarterly business reviews, January 2025.
- Digital Applied — Schema Markup After March 2026 — Analysis of Google’s March 2026 core update and structured data strategy shifts.
- Analyzify — Schema Markup in AI Citations Research — Aggregated findings from academic and industry studies on AI citation lift, including BrightonSEO April 2026 presentation.
Secondary Sources
- Digital Strategy Force — What Schema Markup Gets You Cited by ChatGPT and Google AI Mode in 2026 — HTTP Archive data on JSON-LD adoption; arXiv research on RAG accuracy.
- Tonic Worldwide — Schema Markup and Rich Snippets in 2026 — First Page Sage CTR data; AI Overviews growth analysis.
- GW Content — Structured Data for SEO 2026 — Search Engine Land September 2025 controlled experiment with schema vs. no schema.
Related Articles
How Schema Markup Gets You Rich Snippets (and More Clicks)
Schema Markup Generators: The Complete Guide to AI-Ready Structured Data
Best JSON-LD Schema Markup Generators (2025–2026): Compared, Ranked & Reviewed
Free Schema Markup Tools SEO Experts Use — What Top Performers Do Differently
How Rich Snippets Increase Organic Traffic (With Real Examples)